 Graph Database Market
 2026: Size, CAGR & Vendor Shifts
Updated On : Nov 19, 2026|Base Year : 2025|Pages : 241

Srinwanti Kar
Senior Research Analyst

Sector Data Insights (SDI) is a specialized market intelligence and strategic consulting firm focused on delivering high-quality, data-driven syndicated research reports, industry analysis, competitive intelligence, and advisory solutions. With a strong emphasis on analytical excellence, particularly in life sciences, analytical instrumentation, and related high-tech sectors, Sector Data Insights empowers manufacturers, investors, service providers, researchers, and decision-makers with actionable insights for strategic growth, innovation, and market leadership.
SDI combines deep domain expertise in laboratory and analytical technologies with advanced analytics to provide comprehensive market assessments, technology trend analysis, vendor share data, investment intelligence, supply chain insights, and forward-looking forecasts. Our research supports organizations navigating complex global markets across industries such as life sciences, semiconductors & electronics, consumer goods, materials & chemicals, construction & manufacturing, food & beverages, energy & power, automotive & transportation, ICT & media, aerospace & defense, and BFSI.

+1 2315155523
 Graph Database Market
Srinwanti Kar
Senior Research Analyst

| Year | Market Size |
|---|---|
| 2025 | 3.310 B |
| 2026 | 4.210 B |
| 2027 | 5.350 B |
| 2028 | 6.810 B |
| 2029 | 8.660 B |
| 2030 | 11.02 B |
| 2031 | 14.02 B |

The Graph Database Market covers software platforms and associated services that store, query and analyse data as nodes and relationships (edges) rather than rigid tables. It spans labelled property graph and RDF engines, deployed on-premises or in the cloud, serving fraud analytics, recommendation engines, knowledge graphs and AI context layers.
This analysis covers global graph database software platforms and services across BFSI, healthcare and life sciences, retail and e-commerce, IT and telecommunications, media and entertainment, transportation and logistics, and other industries, split by component, deployment and enterprise size. This analysis does not cover general-purpose relational or document databases, standalone graph visualisation tools, or broader big-data analytics and data-warehouse platforms except where they directly embed graph engine capability.
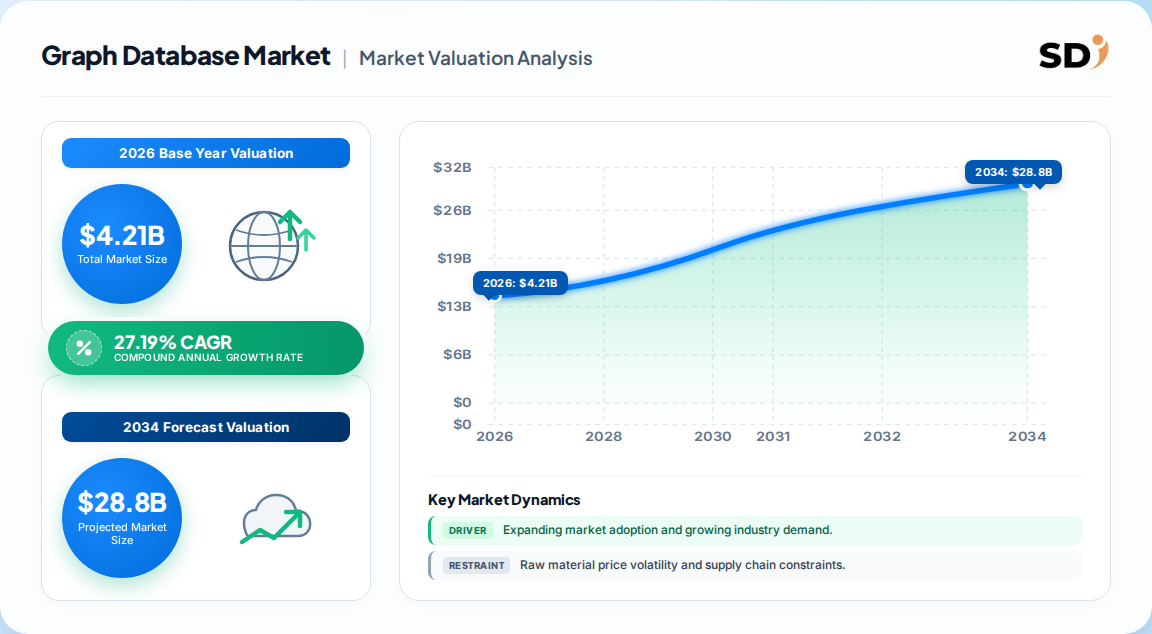
The market is most defensibly sized at USD 4.21 billion for 2026, with a 27.19% CAGR to USD 14.02 billion by 2031 — the most internally consistent estimate once definitions are aligned. Competing published figures diverge mainly on scope, not on direction.
| Estimate | Base year | Horizon | CAGR | Definition / scope | Attribution |
|---|---|---|---|---|---|
| USD 4.21 Bn | 2026 | 2031 | 27.19% | Solutions + services, all deployment and end-user industries | One published estimate (Mordor-style framework) |
| USD 4.97 Bn | 2026 | 2030 | 23.2% | Software + services, incl. RDF and labelled property graph, broad application taxonomy | A competing analysis |
| USD 3.8 Bn | 2025 | 2035 | 19.0% | Platform-led definition with longer horizon and mature-market deceleration | A separate 10-year outlook |
Our analysis suggests the divergence is a horizon and scope artefact rather than a demand disagreement. The 19.0% ten-year figure implicitly assumes a slowdown after 2030 as the installed base matures and hyperscaler pricing compresses licence values. The 27.19% five-year figure better reflects the current inflection — AI context layers and cloud-native migration are driving a genuine step-change in demand. Buyers should anchor budgeting on the 2026–2031 range and treat the 10-year estimate as a maturity-case scenario.
The market segments along four non-geographic axes: component (solutions versus services), deployment (cloud versus on-premises), enterprise size (SMEs versus large enterprises) and end-user industry.
| Parent Segment | Children | 2025 Share / Trend |
|---|---|---|
| Component | Solutions, Services (Managed, Professional) | Solutions 63.10%; services 26.63% CAGR |
| Deployment | Cloud, On-Premises | Cloud 71.50%; 28.92% CAGR |
| Enterprise Size | SMEs, Large Enterprises | Large enterprises 58.70%; SMEs 29.17% CAGR |
| End-User Industry | BFSI, Healthcare & Life Sciences, Retail & E-Commerce, IT & Telecom, Media & Entertainment, Transport & Logistics, Others | BFSI 25.80%; healthcare fastest at 29.66% CAGR |
Two structural observations follow. First, cloud share (71.50%) and services growth together imply a market where buyers increasingly rent capability and buy expertise — pure licence revenue is becoming a smaller slice of wallet. Second, SME growth at 29.17% outpaces large enterprises, indicating the buyer base is broadening from early-adopter enterprises to mid-market operators.
North America leads the Graph Database Market with 36.30% of 2025 revenue, but Asia-Pacific is the fastest-growing region at a 28.74% CAGR — the growth centre of gravity is shifting eastward even as spend concentrates in the US.
| Region | Market Share (%) |
|---|---|
| North America | 0.36% |
| Europe | 0.24% |
| Asia-Pacific | 0.28% |
| Latin America | 0.07% |
| Middle East & Africa | 0.05% |
| Parent Region | Countries Covered |
|---|---|
| North America | USA, Canada, Mexico |
| Europe | Germany, UK, France, Italy, Rest of Europe |
| Asia-Pacific | China, Japan, India, South Korea, Australia, Rest of APAC |
| Latin America | Brazil, Argentina, Mexico, Rest of LATAM |
| Middle East & Africa | Saudi Arabia, UAE, South Africa, Rest of MEA |
This divergence implies a two-speed market. North American buyers are in the optimisation phase — consolidating vendors, negotiating cloud commitments and demanding AI-ready graph features. Asia-Pacific buyers are in the build phase, where national digital-twin and fintech programmes create greenfield graph demand with less legacy lock-in. Vendors that price and package for North American procurement will under-serve APAC's faster, programme-led buying cycles.
Cloud-native adoption and AI pipeline demand are the dominant growth drivers, together contributing more than 15 percentage points of CAGR impact, while a shortage of skilled graph modellers is the single largest restraint at −6.2%.
| Factor | Direction | Evidence strength | Mechanism |
|---|---|---|---|
| Cloud-native enterprise data stacks | Driver (+8.5%) | Medium-term, strong | Serverless graph lowers infra cost; embedded in AWS/Microsoft platforms |
| AI/ML pipelines needing connected context | Driver (+7.2%) | Short-term, strong | Graph RAG and knowledge graphs cut LLM hallucination |
| Digital transformation programmes | Driver (+6.3%) | Medium-term, strong | Broad enterprise modernisation |
| Hyperscaler M&A for graph capabilities | Driver (+4.1%) | Medium-term, moderate | Consolidation raises entry bar, validates category |
| Digital-twin public programmes | Driver (+3.8%) | Long-term, moderate | Government AI budgets fund graph-based simulation |
| Skilled graph modeller shortage | Restraint (−6.2%) | Medium-term, strong | Longer deployment cycles; higher consulting cost |
| Query language interoperability gaps | Restraint (−4.8%) | Short-term, moderate | Cypher/Gremlin/SPARQL fragmentation deters multi-vendor |
The balance favours growth, but with a caveat: driver impacts are directional, not additive. Our analysis suggests the talent constraint is the binding limit on realising AI-driven demand — enterprises can buy graph platforms readily but cannot staff them easily. This is why services outpace software licensing and why professional services firms and managed graph offerings are the underestimated profit pool.
The field is medium-concentration, led by hyperscalers (AWS, Microsoft, Oracle, IBM) and graph specialists (Neo4j, TigerGraph, Stardog, DataStax, Franz). Hyperscalers compete on distribution and bundling; specialists on query performance and modelling depth.
| Vendor | Category | Corestrength |
|---|---|---|
| Amazon Web Services | Hyperscaler | Neptune plus ecosystem bundling, Bedrock integration |
| Microsoft | Hyperscaler | Fabric integration, enterprise distribution |
| Oracle | Hyperscaler / incumbent | Database estate cross-sell |
| IBM | Incumbent | Enterprise governance and hybrid deployment |
| Neo4j | Specialist | Cypher standard, developer community, AWS Bedrock/Fabric tie-ins |
| TigerGraph | Specialist | High-scale parallel graph analytics |
| DataStax, Stardog, Franz | Specialist | Enterprise knowledge graph and semantic layers |
Specialists retain a moat in modelling depth and developer loyalty, but that moat is thinning as hyperscalers embed graph features into existing cloud contracts. The strategic risk for buyers is not choosing the weaker engine — it is choosing a vendor whose roadmap is not aligned with the hyperscaler ecosystem they already run. Vendor viability now depends as much on partnership topology as on query benchmarks.
Selection should hinge on four criteria, in order: query performance against your actual graph shape, ecosystem fit with your existing cloud contract, portability of the query language, and the depth of the vendor's service partner network. Performance claims rarely survive contact with real data, so insist on a proof-of-concept on your own graph, not a benchmark.
Procurement risk concentrates in three areas. First, interoperability: with no fully ratified graph query language standard, migration across engines carries real re-modelling cost — treat language choice as a multi-year lock-in decision. Second, egress and multi-cloud data movement costs, which can erode business cases for hybrid graph deployments. Third, skills: the modeller shortage means implementation timelines and consulting fees are volatile; budget for managed services rather than assuming in-house capability.
Regulatory compliance, particularly AML/KYC in BFSI and data lineage in healthcare, is a genuine differentiator rather than a tick-box — graph-native lineage and auditability are increasingly procured as compliance infrastructure, not analytics. Buyers in regulated sectors should evaluate audit trails and data-residency controls alongside query speed.
The balance of evidence favours the higher-growth reading of this market: a 27.19% CAGR through 2031 is more defensible than the 19.0% long-horizon view, because the demand drivers — AI context layers, cloud migration and digital-twin programmes — are early-cycle, not late. The strongest counter-argument is that hyperscaler bundling compresses specialist licence pricing faster than volume grows, capping value even as adoption expands. That risk is real, but it shifts value to services rather than destroying it.
Our analysis suggests the market's centre of profit is migrating from engine licensing to implementation and managed operations, precisely because the talent constraint is the binding limit on adoption. Vendors and investors who model this market as a software-licence business will systematically underweight the services opportunity, and buyers who assume they can self-implement will under-budget timelines.
Actionable strategy:
What would change this conclusion: a ratified graph query language standard would reduce lock-in and accelerate adoption beyond forecast; conversely, a sharp hyperscaler price war on graph features would compress licence revenue and pull the CAGR toward the lower 19–23% band.
| Aspects | Details |
|---|---|
| Study Period | 2020-2034 |
| Base Year | 2025 |
| Estimated Year | 2026 |
| Forecast Period | 2026-2034 |
| Historical Period | 2020-2025 |
| Growth Rate | CAGR of 27.19% from 2020-2034 |
| Segmentation |
|
The graph database market is valued at USD 4.21 billion in 2026, growing from USD 3.31 billion in 2025. It is projected to reach USD 14.02 billion by 2031 at a 27.19% CAGR, driven by AI context layers and cloud-native data stacks.
Asia-Pacific is the fastest-growing region at a 28.74% CAGR through 2031, while North America remains the largest with 36.30% of 2025 revenue. APAC growth is driven by digital-twin programmes and fintech adoption.
Cloud deployment dominates, holding 71.50% of 2025 revenue and growing at a 28.92% CAGR to 2031. Serverless graph offerings embedded in hyperscaler platforms are accelerating the shift away from on-premises deployment.
Leading vendors include Amazon Web Services, Oracle, Microsoft, Neo4j and TigerGraph, alongside IBM, SAP, DataStax and Stardog. The market is medium-concentration, with hyperscalers competing on distribution and specialists on query performance and modelling depth.
The biggest restraint is a shortage of skilled graph data modellers, estimated at a −6.2% impact on CAGR. Query language interoperability gaps between Cypher, Gremlin and SPARQL also deter multi-vendor strategies and raise migration risk.
Our rigorous research methodology combines multi-layered approaches with comprehensive quality assurance, ensuring precision, accuracy, and reliability in every market analysis.
Our research programme applies a 70/30 primary-to-secondary split, prioritising direct verification of demand and deployment patterns. We conducted in-depth interviews across the graph data value chain: platform vendors, cloud infrastructure providers, systems integrators, managed service providers and enterprise end-users. Within these organisations we engaged decision-makers including Chief Data Officers, VP-level Data Platform owners, Heads of Analytics Engineering and Enterprise Architecture Directors, ensuring that both buying intent and technical implementation realities were captured.
| Stakeholder Role | Interview Share (%) |
|---|---|
| Chief Data & Analytics Officers | 35% |
| Data Platform & Architecture Leads | 30% |
| Procurement & Vendor Management | 20% |
| Compliance & Risk Officers | 15% |
| Company Type | Representation (%) |
|---|---|
| Graph Platform & Database Vendors | 40% |
| Cloud & Hyperscaler Providers | 25% |
| Systems Integrators & MSPs | 20% |
| Enterprise End-Users | 15% |
Secondary validation draws on official multilateral and standards sources rather than competitor commentary. We benchmark against Eurostat and US ITC digital-services trade data, corporate annual filings and SEC disclosures from listed database and cloud vendors, patent filings in graph query and knowledge-graph domains, and technical standards work from recognised industry associations. These sources anchor demand estimates in observable commercial and regulatory activity.
We triangulate two parallel models. The top-down model allocates macroeconomic IT and data-management spend to the graph segment using industry mix and cloud adoption ratios. The bottom-up model builds from vendor capacity, licence and consumption pricing, and end-use deployment counts. Divergence between the two is reconciled at the segment level before regional roll-up.
| Dimension | Analytical Scope | Methodology Applied | Validation Level |
|---|---|---|---|
| Base-Year Market Size | Value in USD for base year | Bottom-up production & revenue triangulation | High |
| Forecast Horizon | Multi-year compound projection | Historical CAGR, regression analysis & demand elasticity | High |
| Regional Distribution | Regional share breakdown | Cross-border trade flow analysis & regional consumption | High |
| Competitive Landscape | Leading market players | Annual reports, capacity mapping & commercial filings | High |